
The more I learn Python, the more I notice repetitive SEO tasks that probably don’t need to stay repetitive.
I’m not trying to automate SEO itself.
Strategy still needs judgement. Content still needs thought. Clients still need context. Search changes too quickly for me to trust every decision to a script.
What I do want to automate is the boring stuff around the thinking.
The checks.
The cleanup.
The comparisons.
The repetitive data work that somehow turns 15 minutes into two hours.
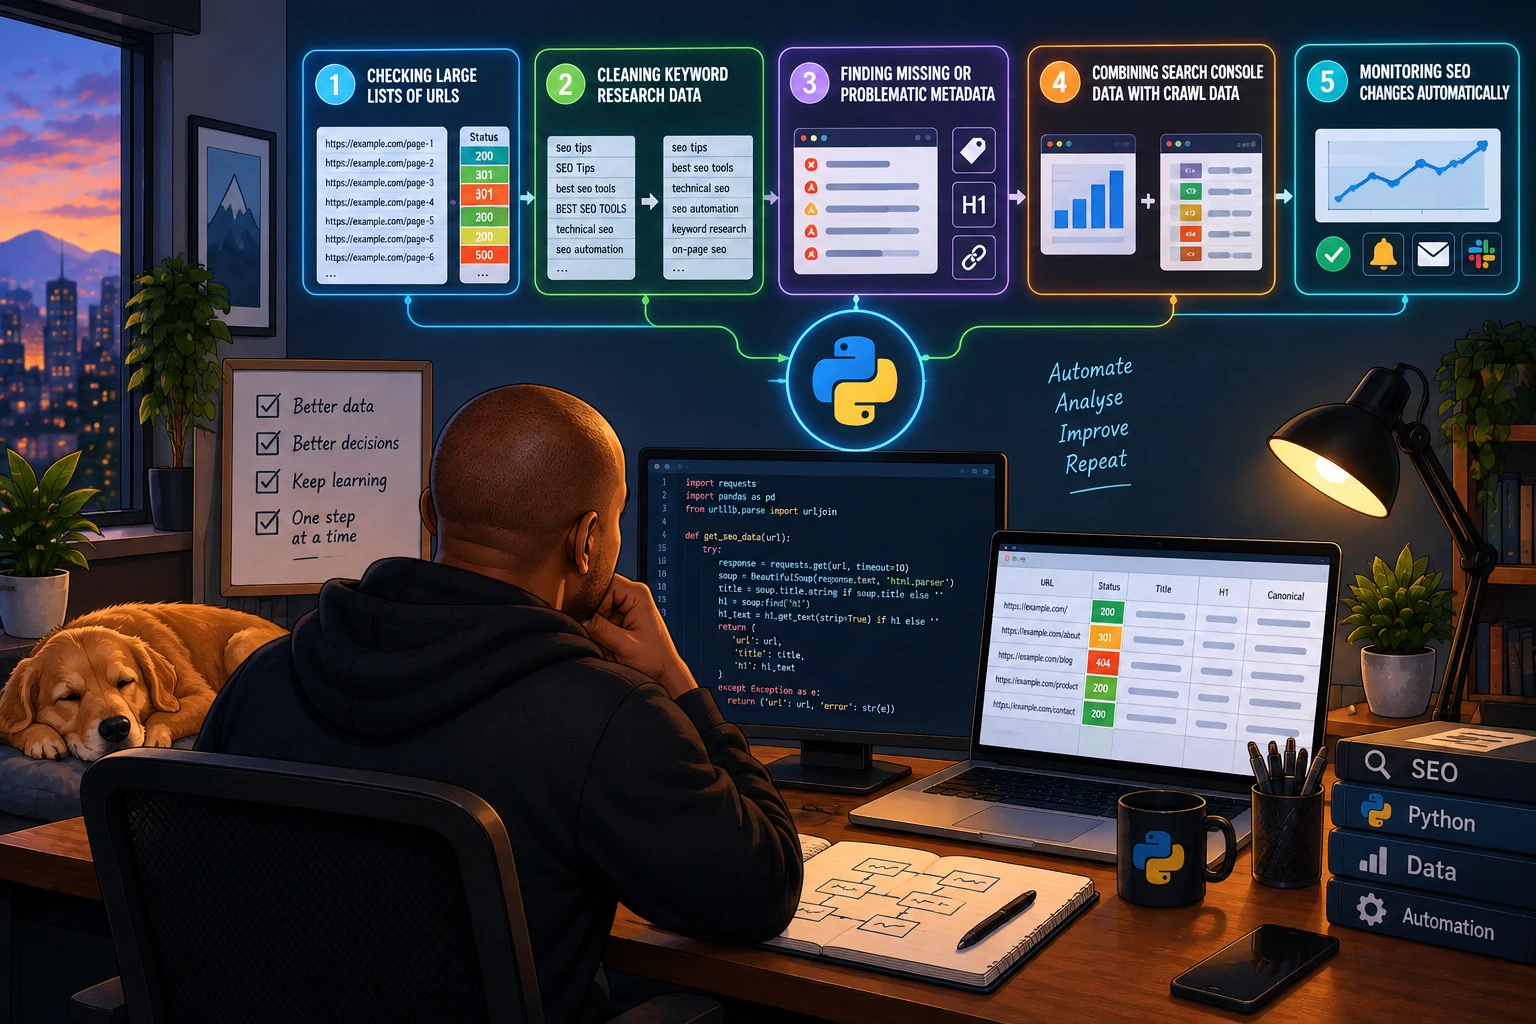
So these are five SEO tasks I want to get better at automating with Python.
1. Checking Large Lists of URLs
This is the obvious one.
SEO involves a ridiculous amount of URL checking.
You get a spreadsheet with hundreds or thousands of pages and need to know:
Which URLs return a 200?
Which redirect?
Which are broken?
What is the final destination?
Does the page have a title tag?
Is there an H1?
What canonical is being used?
I’ve already started experimenting with a simple Python script that does some of this.
The basic idea is straightforward:
Give Python a list of URLs.
Let it request each page.
Extract the information I care about.
Export the results.
It isn’t going to replace a crawler like Screaming Frog, and I don’t want it to.
I’m more interested in building small checks for specific situations.
Maybe a client sends me 600 URLs and I only need five pieces of information from each one.
That’s where a simple script starts making sense.
2. Cleaning Keyword Research Data
Keyword research usually produces messy spreadsheets.
You export data from one tool.
Then another.
Then Search Console.
Then maybe competitor data.
Suddenly the same keyword appears three times with slightly different formatting.
Capitalisation is inconsistent.
There are duplicates.
Some rows are irrelevant.
Maybe you need to remove branded terms.
Maybe you want to group similar phrases.
And before you’ve done any actual analysis, you’ve spent 45 minutes cleaning a spreadsheet.
I want Python to take more of that work away.
Things like:
Removing duplicates.
Normalising text.
Filtering keywords based on rules.
Combining multiple CSV files.
Sorting data by volume or intent.
Finding terms that appear across multiple datasets.
None of these tasks are particularly exciting.
That’s exactly why I want to automate them.
I’d rather spend my time deciding which opportunities matter than manually fixing spreadsheet formatting.
3. Finding Missing or Problematic Metadata
This is another task that becomes painful at scale.
Checking one page title is easy.
Checking 5,000 isn’t.
I’d like to build scripts that can quickly flag things such as:
Missing title tags.
Duplicate titles.
Very short titles.
Very long titles.
Missing meta descriptions.
Duplicate meta descriptions.
Missing H1s.
Multiple H1s.
Missing canonicals.
Eventually, I could make those checks more specific.
For example, if I’m working on a multi-location website, maybe I want to know which location pages don’t mention their city in the title or H1.
Or perhaps I want to compare the live title tag against a recommended title stored in another file.
That’s where custom scripts become more interesting than generic audits.
You’re not just checking whether something exists.
You’re checking whether it matches the rules of that particular project.
4. Combining Search Console Data With Crawl Data
This is probably one of the projects I’m most interested in.
Crawl data tells you what exists on the website.
Search Console tells you how Google Search is interacting with those pages.
Those datasets become much more useful when you combine them.
Imagine having one file containing:
URL.
Status code.
Title.
Canonical.
Word count.
Indexability.
Then adding:
Clicks.
Impressions.
CTR.
Average position.
Now you can start asking better questions.
Which indexable pages receive no impressions?
Which pages get impressions but almost no clicks?
Which high-performing pages have weak title tags?
Are broken URLs still receiving search demand?
Do pages with certain technical issues also have poor search performance?
You can already do a lot of this with spreadsheets and SEO platforms.
But I want to understand how to build the workflow myself.
Pull the data.
Join the datasets.
Apply rules.
Produce the output I actually need.
That feels like a genuinely useful Python skill.
5. Monitoring SEO Changes Automatically
This one could become much more ambitious.
I’d love to build small monitoring scripts that check important things regularly.
Not everything.
Just the things where discovering a problem quickly matters.
Maybe a set of important URLs suddenly stops returning 200 status codes.
Maybe a canonical changes.
Maybe a noindex tag appears on an important page.
Maybe a title tag gets replaced.
Maybe robots.txt changes.
Maybe a page disappears.
Instead of discovering the issue during the next audit, a script could identify that something changed.
That starts moving Python from analysis into monitoring.
And I think that’s where automation becomes particularly useful.
You’re not simply doing the same task faster.
You’re creating a process that can keep watching something while you’re focused elsewhere.
I Don’t Want to Automate Every SEO Task
This is important.
Just because something can be automated doesn’t mean it should be.
I don’t want Python deciding whether a piece of content is genuinely useful.
I don’t want a script making strategic recommendations without context.
I don’t want automation creating 10,000 pages because some spreadsheet said there were 10,000 keywords.
Those decisions require more than rules.
They require judgement.
What I want Python to handle is the work underneath those decisions.
Gather the information.
Clean it.
Compare it.
Flag problems.
Then give me something useful to think about.
AI Makes These Projects Easier to Start
I’m also learning Python at probably the easiest time in history to learn programming.
When I’m stuck, I can ask AI to explain an error.
I can show it a section of code and ask what it does.
I can ask for different ways to solve the same problem.
That’s incredibly useful.
But I’m trying not to skip the understanding part.
If AI generates a script that checks 5,000 URLs, I still want to understand why the loop works.
What happens when a request fails?
Where is the data being stored?
Why did we use that particular library?
What happens if the input file changes?
Otherwise, I’m not really learning Python.
I’m just operating a code generator.
My Goal Is to Build a Small SEO Toolkit
Eventually, I’d like to have a collection of small scripts.
Nothing fancy.
One checks URLs.
One cleans keyword files.
One analyses metadata.
One combines datasets.
One monitors important pages.
Maybe another pulls data from an API.
Individually, none of them would be revolutionary.
Together, they could become a useful personal SEO toolkit.
More importantly, I’d understand how they work.
The Real Automation Opportunity Is Between the Tools
The more I think about Python and SEO, the less interested I am in replacing existing SEO platforms.
Those tools are already incredibly powerful.
What interests me is everything that happens between them.
Export something from one tool.
Clean it manually.
Add information from another.
Create some formulas.
Copy something into a new spreadsheet.
Filter it.
Repeat next month.
Those little gaps are everywhere.
That’s where I think Python can save me the most time.
Not by replacing SEO tools.
By connecting the work around them.
And that’s what I want to learn how to build.
